Zhiyuan You | 尤志远
The Chinese University of Hong Kong |
|
Biography
I am a Ph.D. candidate at Multimedia Laboratory (MMLab), The Chinese University of Hong Kong (CUHK). I am supervised by Prof. Tianfan Xue and Prof. Chao Dong. I also work closely with Dr. Jinjin Gu.
Prior to that, I received my M.Eng. from Shanghai Jiao Tong University (SJTU) in 2023, supervised by Prof. Xinyi Le and Prof. Yu Zheng, and my B.Eng. from the same university in 2020.
I previously conducted research at several leading institutions, including ByteDance Seed, Adobe, Shanghai AI Lab, Horizon Robotics, and SenseTime.
My current research interest mainly lies in generation models, multi-modal systems, vision-centric agent, and low-level vision.
News
[2026.09] Three papers (One Position Track) to appear in NeurIPS 2026.
[2026.07] One paper to appear in ACM MM 2026.
[2026.05] One paper to appear in ICML 2026 (Oral).
[2026.03] One paper to appear in ACL 2026.
[2026.03] One paper to appear in PR.
[2026.02] Three papers (One Findings Track) to appear in CVPR 2026.
[2025.11] One paper to appear in TIP.
[2025.11] End of my internship at Adobe — heartfelt thanks to all the teams.
[2025.09] Two papers (One Datasets & Benchmarks Track) to appear in NeurIPS 2025.
[2025.08] One paper to appear in TOG, SIGGRAPH Asia 2025 (Journal Track).
[2025.07] We win the Championship in the VQualA 2025 DIQA Challenge (ICCV 2025 Workshop).
[2025.03] One paper to appear in TPAMI.
[2025.02] Two papers to appear in CVPR 2025 (One Highlight). See you in Nashville.
[2025.01] One paper to appear in ICLR 2025.
[2024.12] One paper to appear in AAAI 2025 (Oral).
[2024.09] One paper to appear in NeurIPS 2024 (Spotlight).
[2024.08] One paper to appear in TMLR.
[2024.07] One paper to appear in ECCV 2024. See you in Milan.
[2023.08] I become a Ph.D. student at MMLab in The Chinese University of Hong Kong.
[2023.03] I graduate and receive my Master's degree from Shanghai Jiao Tong University.
[2022.09] One paper to appear in NeurIPS 2022 (Spotlight).
[2022.09] One paper to appear in ICONIP 2022 (Oral).
[2022.08] One paper to appear in WACV 2023.
[2020.07] I graduate and receive my Bachelor's degree from Shanghai Jiao Tong University.
Publications
*: Equal Contribution, †: Corresponding Author
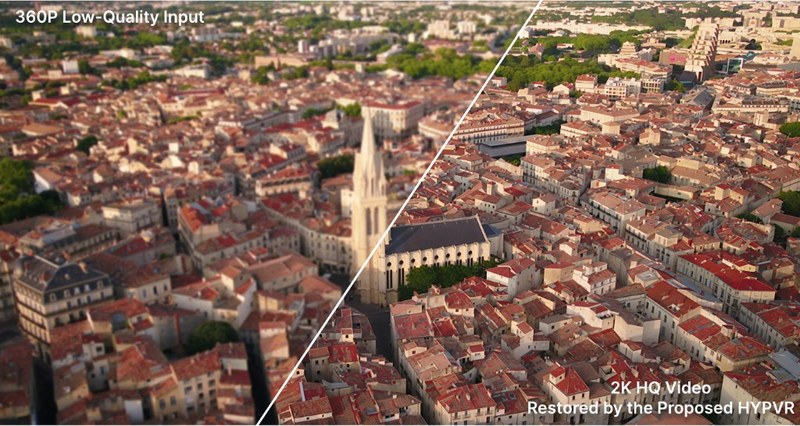
[Paper]
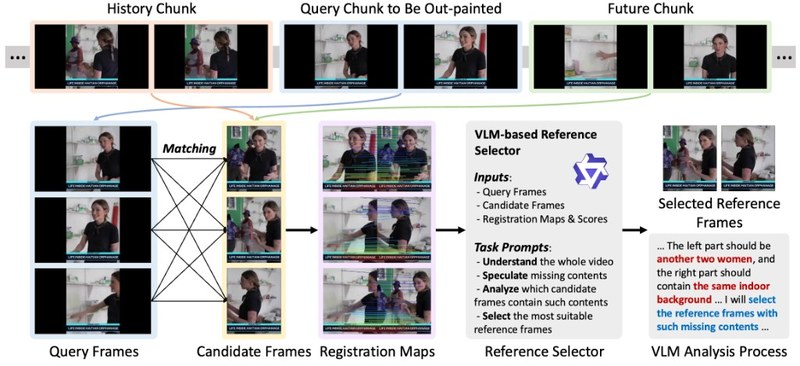
[Paper]
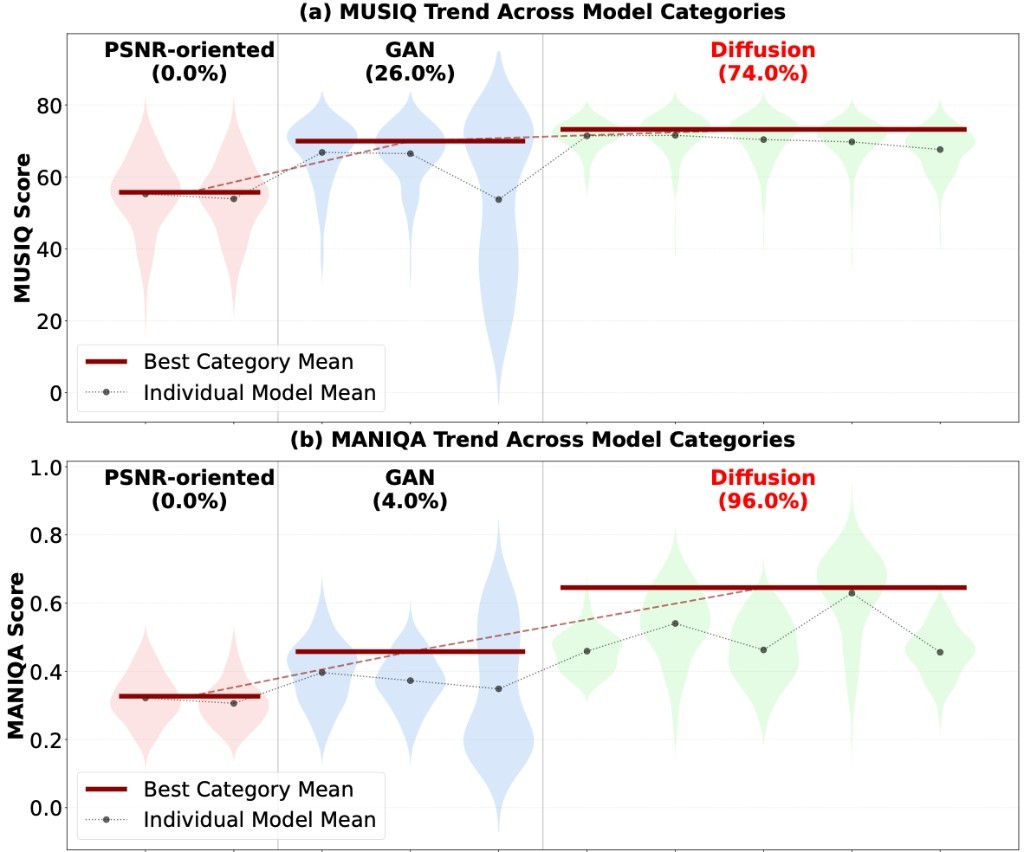
[Paper]
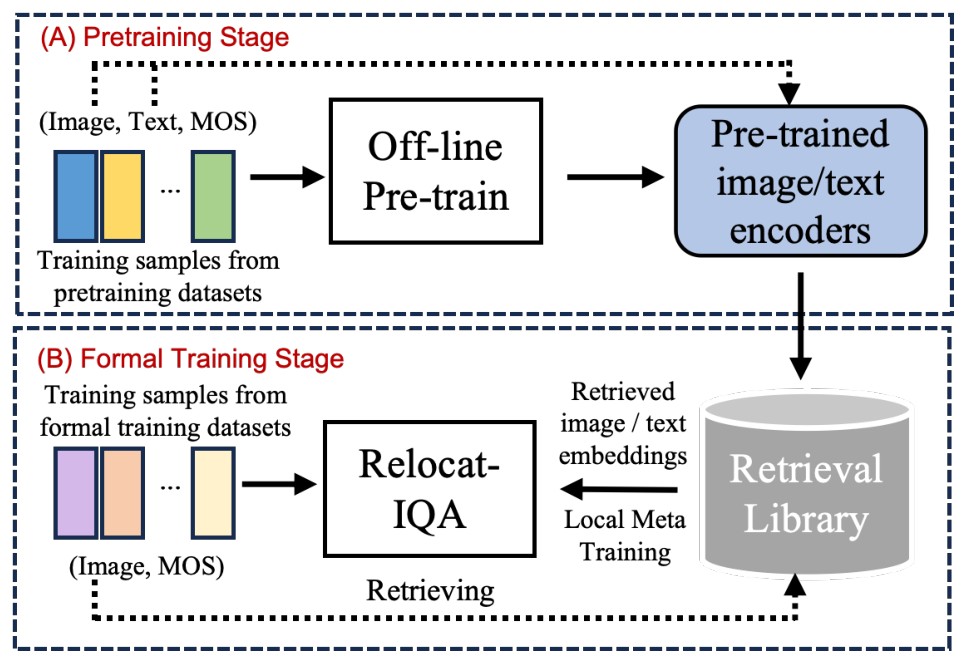
[Paper]

[Project Page] [Paper] [Code]
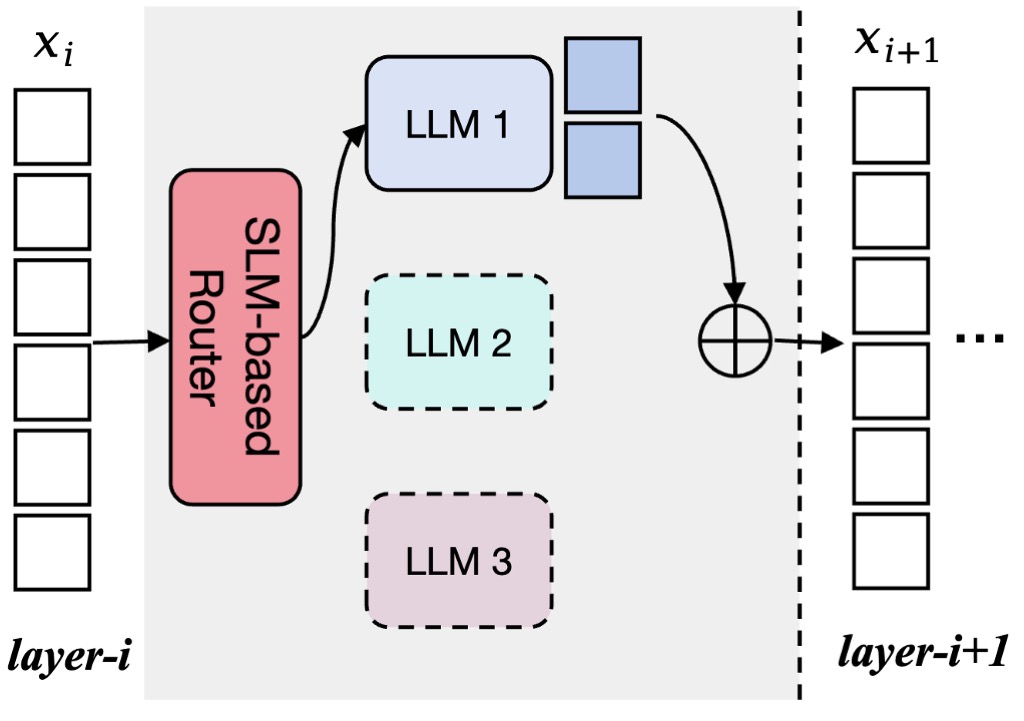
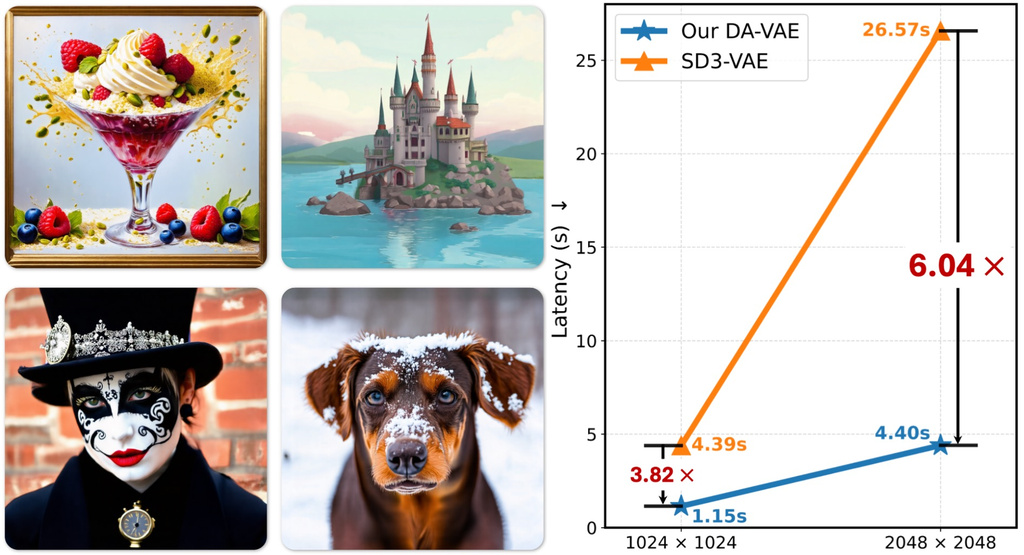
[Project Page] [Paper] [Code]
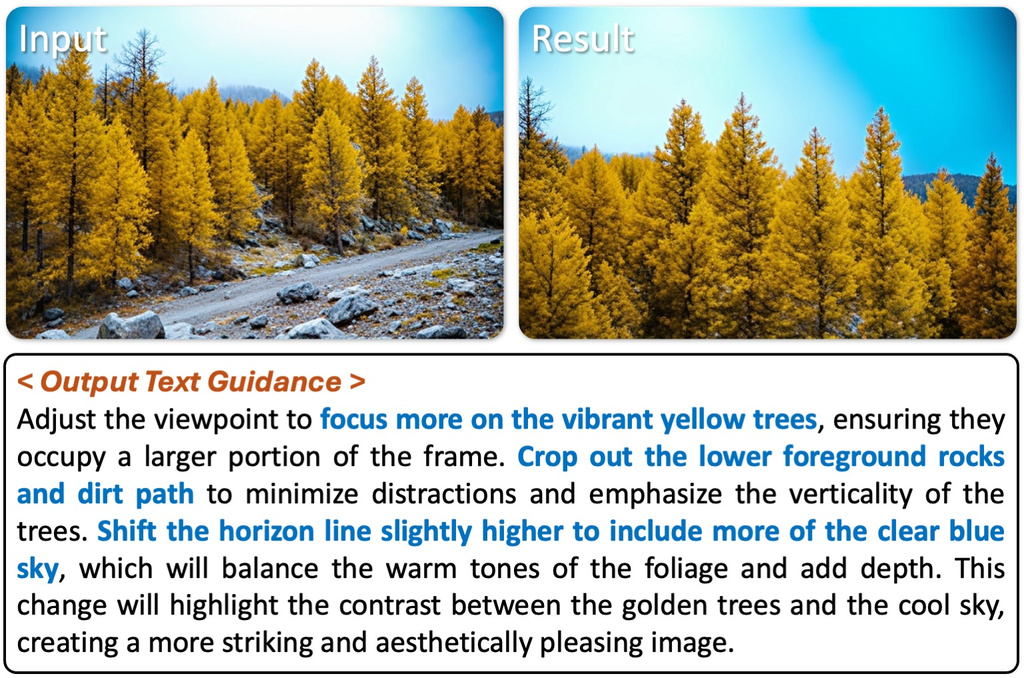
[Project Page] [Paper] [Code]
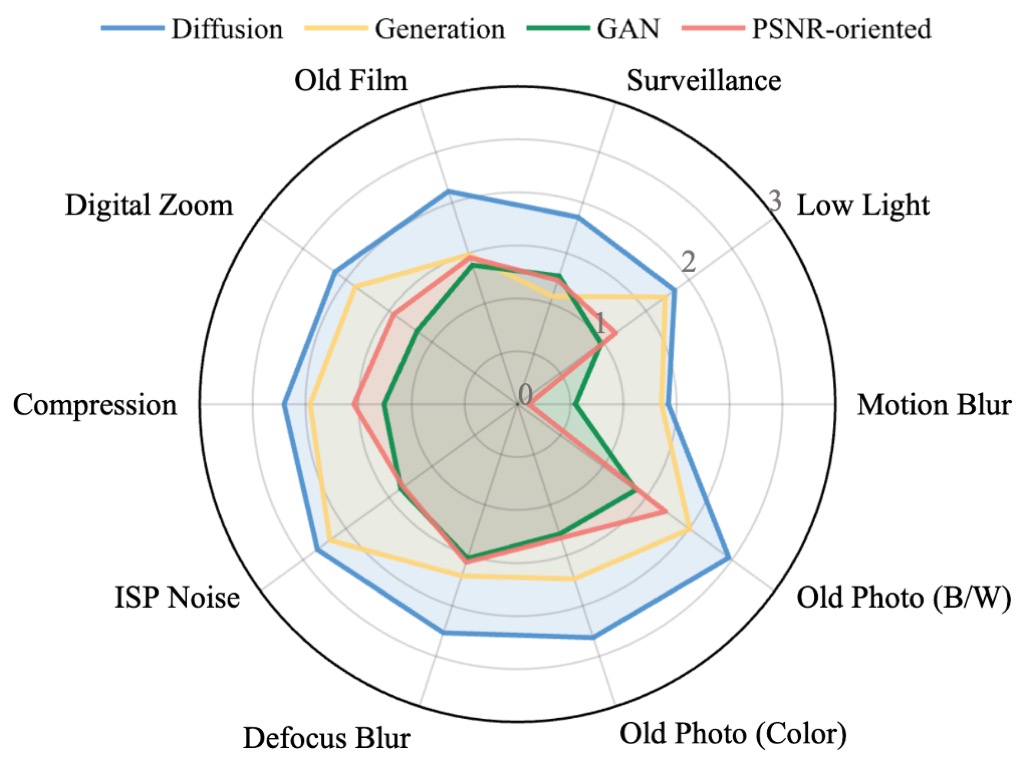
[Project Page] [Paper] [Code]
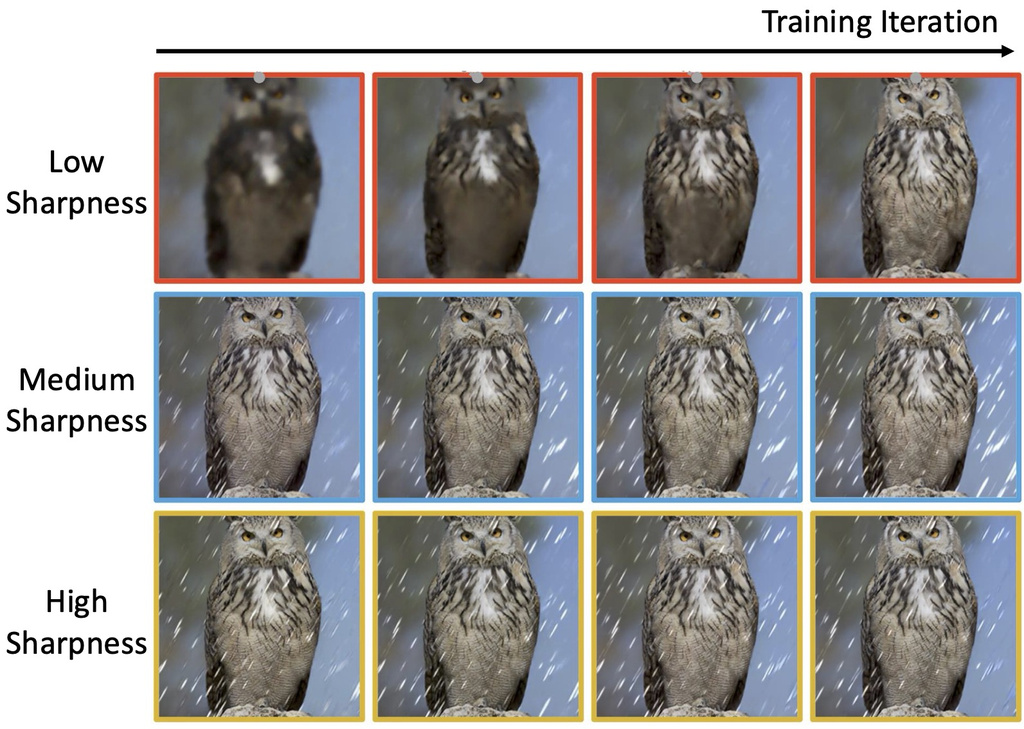
[Paper]
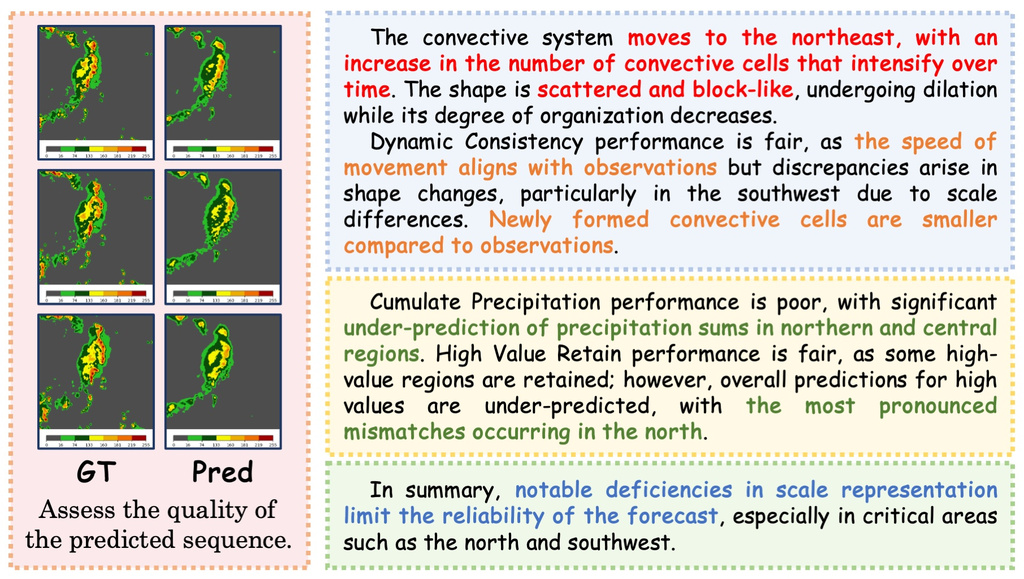
[Project Page] [Paper] [Code] [Data]
[Project Page] [Paper] [Code] [Online App] [CCTV News (央视新闻直播间报道)]
[Project Page] [Paper] [Code] [Data]
[Project Page] [GitHub Page] [Paper] [Code] [Demo: HuggingFace / OpenXLab]
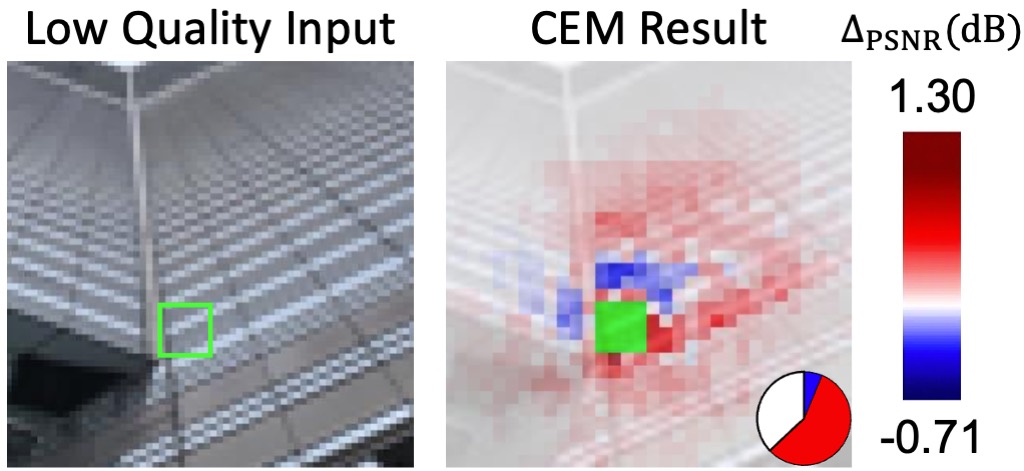
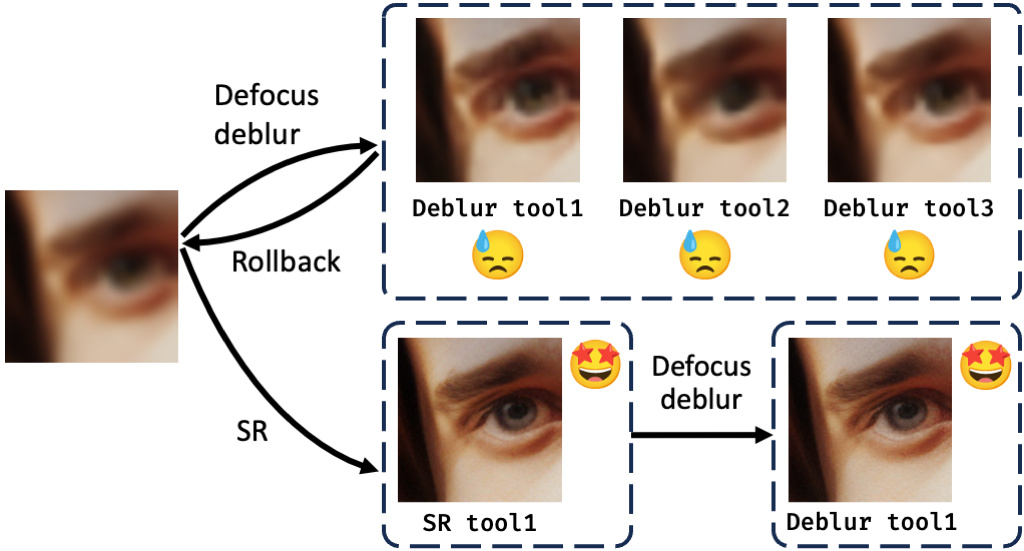
[Project Page] [Paper] [Code]
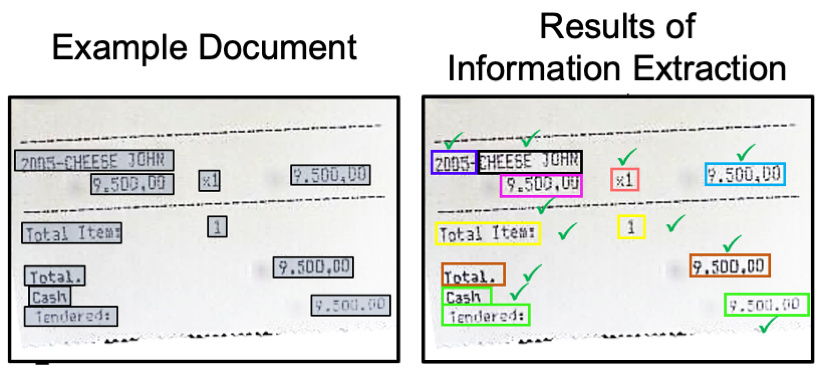
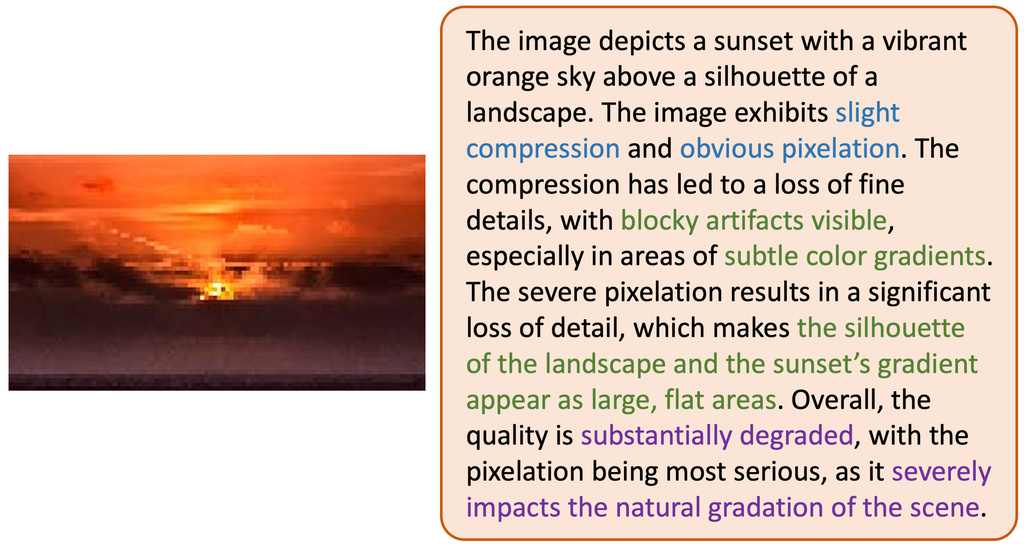
[Project Page] [Paper] [Code] [Data]
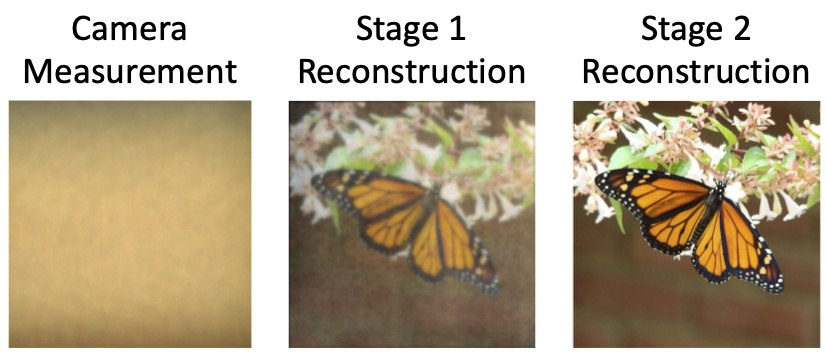
[Project Page] [Paper] [Code]
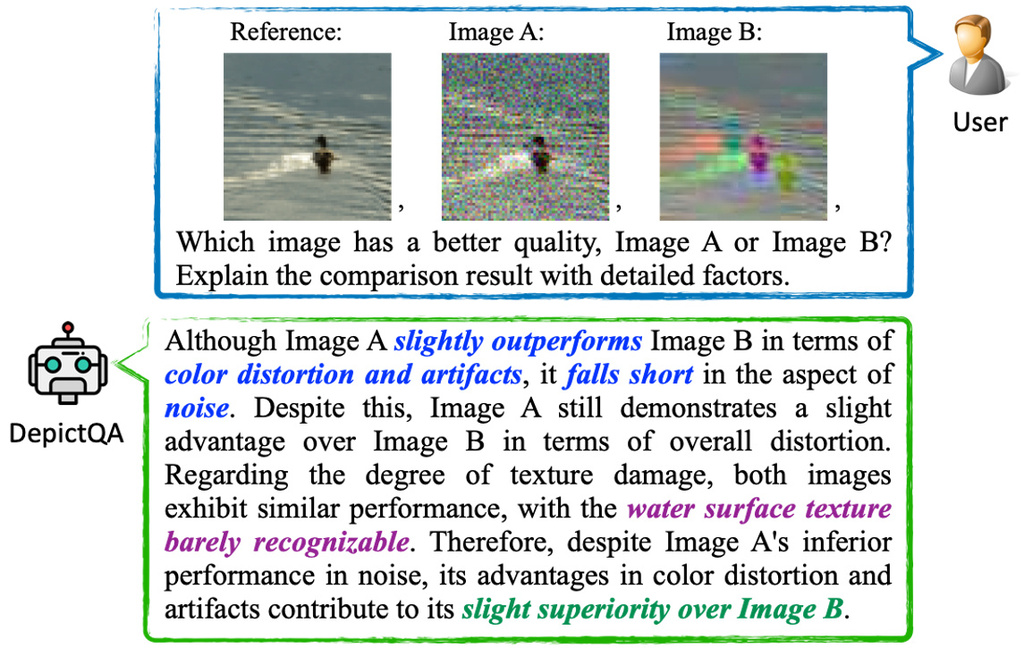
[Project Page] [Paper] [Code] [Data]
[Paper]
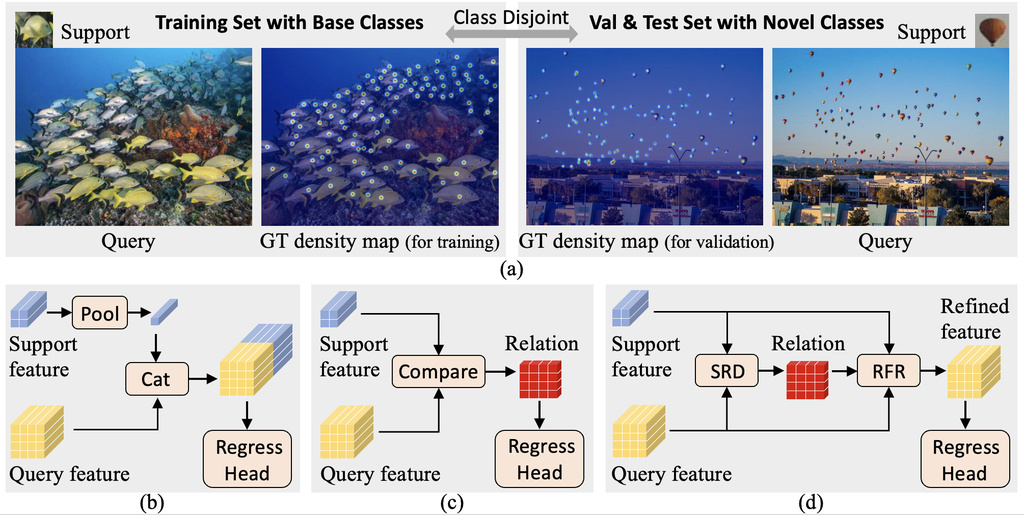
[Paper]
Education
 |
Ph.D. Candidate at Multimedia Laboratory (MMLab) @ The Chinese University of Hong Kong Aug. 2023 - Current GPA: 3.82 / 4.0 Advisor: Prof. Tianfan Xue and Prof. Chao Dong |
 |
M.Eng. with Honor @ Shanghai Jiao Tong University Sep. 2020 - Mar. 2023 GPA: 3.76 / 4.0 Advisor: Prof. Xinyi Le and Prof. Yu Zheng |
|
B.Eng. with Honor @ Shanghai Jiao Tong University Sep. 2016 - Jun. 2020 GPA: 89.36 / 100, Ranking: 5 / 148 Advisor: Prof. Xinyi Le |
Experience
 |
Research Intern @ ByteDance Seed Current Team: Seedance Team Mentor: Dr. Zhaoyang Huang and Dr. Feng Wang |
 |
Research Scientist Intern @ Adobe Jul. 2025 - Nov. 2025 Team: Marc Levoy's NextCam Team Mentor: Dr. Zhoutong Zhang, Dr. Ke Wang, and Dr. He Zhang |
 |
Research Intern @ Shanghai Artificial Intelligence Laboratory May. 2024 - Apr. 2025 Mentor: Prof. Chao Dong |
 |
Research Intern @ Horizon Robotics Nov. 2022 - Mar. 2023 Mentor: Dr. Yuelong Yu |
 |
Research Intern @ SenseTime Dec. 2020 - Nov. 2022 Mentor: Mr. Kai Yang |
Academic Service
Journal Reviewer
- IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)
- International Journal of Computer Vision (IJCV)
- IEEE Transactions on Image Processing (TIP)
- IEEE Transactions on Multimedia (TMM)
- IEEE Transactions on Knowledge and Data Engineering (TKDE)
- IEEE Transactions on Neural Networks and Learning Systems (TNNLS)
- IEEE Transactions on Systems, Man, and Cybernetics: Systems (TSMCS)
- IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)
- Pattern Recognition (PR)
- Neural Networks (NN)
Conference Reviewer
- Computer Vision and Pattern Recognition (CVPR)
- International Conference on Computer Vision (ICCV)
- European Conference on Computer Vision (ECCV)
- Neural Information Processing Systems (NeurIPS)
- International Conference on Machine Learning (ICML)
- International Conference on Learning Representations (ICLR)
- Association for the Advancement of Artificial Intelligence (AAAI)
- ACM Multimedia (MM)
- Winter Conference on Applications of Computer Vision (WACV)
- British Machine Vision Conference (BMVC)
Awards
- SJTU Excellent Master Dissertation, 2023
- SJTU Outstanding Graduate (Postgraduate), 2023
- National Scholarship, 2022
- SJTU Outstanding Graduate (Undergraduate), 2020
| © Zhiyuan You | Last update: August 2026 |